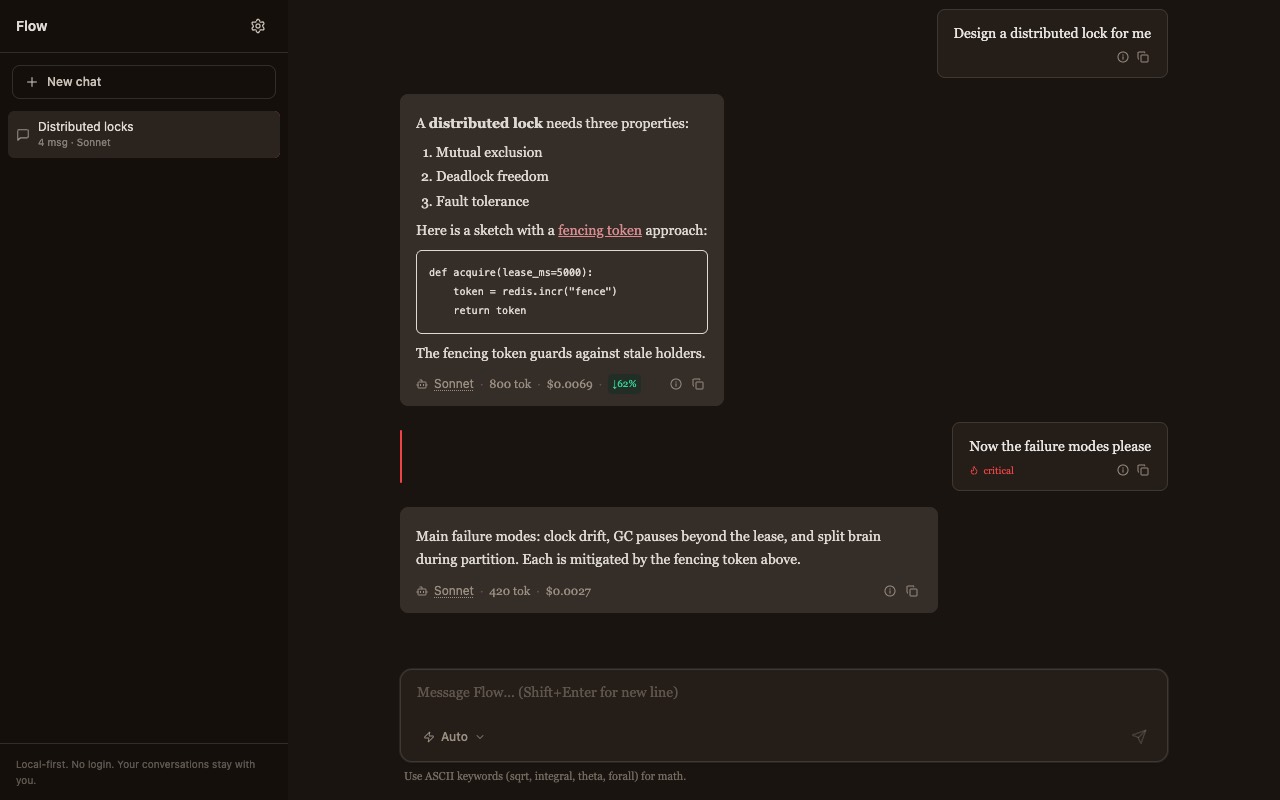
Every reply is labelled with the model that answered, its tokens, and what it cost.
One chat app that puts you in charge. The right model is chosen for you — and you watch what each reply saves you. Your conversations move with you, and nothing gets compressed or thrown away. Flow is free — bring your own provider keys and pay your providers directly.
500 routed prompts included on the free Kongen key — bring your own provider keys and pay your providers directly.
Every reply is labelled with the model that answered, its tokens, and what it cost.
You send a prompt. Kongen Logic scores how much reasoning it needs. The model best suited to the job answers. You see what it cost.
That's the whole loop — and the part that makes it different from an LLM-judge router is what doesn't happen: your prompt isn't handed to a second AI model to decide where it should go.
Save money. Save time. Waste less compute.
When you send a prompt on Auto, Flow sends that prompt's text to Kongen, which scores how much reasoning it needs.
The score picks the model best suited to the job: a light, fast model for "reformat this list," a frontier model for "prove this bound." Pin a model instead and pinned prompts are never sent to Kongen. If scoring is ever unreachable, Flow falls back to your default model and says so.
Model answers never go to Kongen. They stream provider → browser, using your own key. Kongen scores questions; it never sees answers or conversations.
Each reply shows the routing decision and an estimated cost, so the savings are something you can watch, not something you have to trust.
A common pattern in "smart routing" — the LLM-judge approach — decides where your prompt should go by asking another AI model. That means a second inference call before you get any answer: it's slower, it costs its own tokens, and it sends your prompt to yet another model just to make a decision.
Kongen Logic doesn't do that. Its scoring is pattern-based, in-process analysis — it reads the reasoning depth of your prompt by structure, not by asking a language model. No extra LLM call sits between you and your answer.
| LLM-judge router (calls a second model) | Kongen Logic | |
|---|---|---|
| How the routing decision is made | A second LLM is asked to judge the prompt | Pattern-based scoring (in-process computation) |
| Extra LLM inference call? | Yes — one before you get an answer | No |
| Sends your prompt to another model? | Yes — to the judge model | No — scored by computation, not read by a second model* |
| Added token cost for deciding | Yes — the judge call burns tokens | No extra model tokens (scoring costs 1 KT) |
| Speed | Waits on a second model round-trip | No second-model round-trip |
* Your prompt text is sent to Kongen for the scoring step — the claim is "no additional LLM," not "nothing is sent." See step 1.
You save money as a consequence — trivial prompts stop hitting frontier pricing. Savings are estimated vs always using the latest frontier model of your providers.
The mechanism is right-sizing: a one-line reformat doesn't need a frontier model, so it doesn't get one. The spend that used to go to "send everything to the biggest model" shrinks to the prompts that actually need that model.
The proof surface is in the app, not the ad copy. Each reply shows an estimated cost, and Flow keeps a running, on-device estimated-savings counter labeled "est." — so the number you act on is your own measured usage, not a marketing promise.
Scoring itself is inexpensive and honest about its cost: each Auto prompt costs 1 Kongen Token (KT) to score — your free routed prompts are those tokens — and prompts on a pinned model cost nothing, because they're never scored.
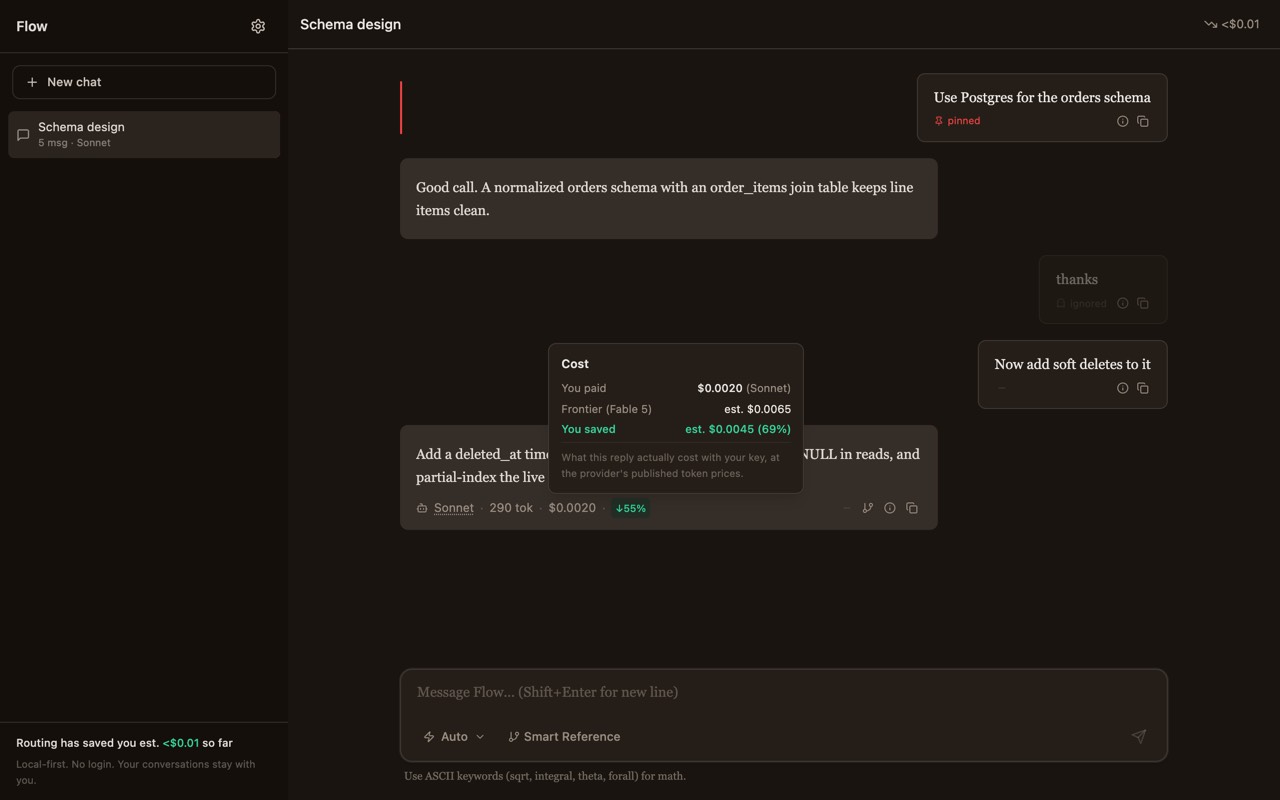
The proof is in the app: each reply shows what it cost and an estimated saving, all labelled “est.”
Right-sizing has a second consequence beyond your bill: less wasted computation. Sending "fix this typo" to a frontier model spends far more computation than the task needs. Matching the model to the prompt means the heavy models run only when the work calls for them.
That's the whole claim, stated as mechanism: don't burn a frontier model on "fix this typo." Right-sized compute, per prompt. Waste less compute.
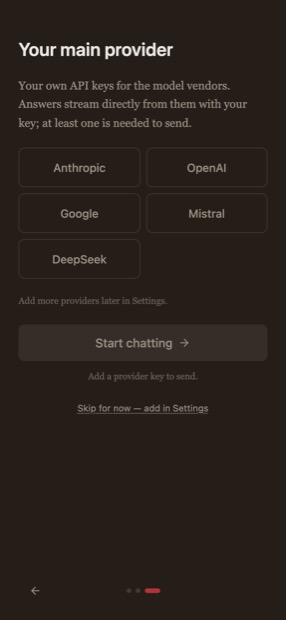
Add a provider key and start chatting. Answers stream straight from the provider with your key. Add more providers later in Settings.
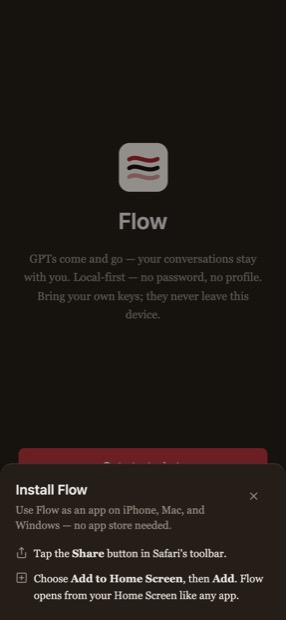
Install it like an app on iPhone, Mac and Windows — no app store needed.
Tap a card for the detail.
Flow runs on a free Kongen key. The same key powers the Kongen API — when you're ready to build, pip install kongenlabs.